My Visit To Chicago

Last Friday I gave a talk at UChicago in their Weekly Morphology & Syntax Workshop. My slides are below:

It had been a while since I’d presented my own work anywhere, so there was a process of “learning how to do this again” involved—which was interesting—and I didn’t fully know what I was going to say until about 3 hours before the talk.

My topic was the theoretical explanation of coordination, comparing Parallel Derivation—which I used to explain adjunction—with Chomsky et al‘s FormSet[1]FormSet is a refinement of the earlier FormSequence. Most comparisons with FormSet also apply to FormSequence.. I have been thinking about the application of Parallel Derivation (PD) to coordination for as long as I’ve had the idea for PD, and about its comparison with FormSet since I first read a description of its precursor but, as is always the case, I discovered a few things through the act if writing these thoughts down and an expressing them to to other syntactiticans.

The next thing to do, I guess, is to write these discoveries down and express them to other syntacticians.

Notes

Notes
↑1 FormSet is a refinement of the earlier FormSequence. Most comparisons with FormSet also apply to FormSequence.

The DP Hypothesis—a case study of a sticky idea

Recently, in service of a course I’m teaching, I had a chance to revisit and fully engage with what might be the stickiest idea in generative syntax—The DP hypothesis. For those of you who aren’t linguists, the DP hypothesis, though highly technical, is fairly simple to get the gist of based on a couple of observations:

Observation 1: Words in sentences naturally cluster together into phrases like “the toys”, “to the store”, or “eat an apple.”

Observation 2: In every phrase, there is a single main word called the head of the phrase. So, for instance, the head of the phrase “eat an apple” is the verb “eat.”

These observations are formalized in syntactic theory, so that “eat an apple” is labeled a VP (Verb Phrase), while “to the store” is a PP (Preposition Phrase). Which leads us to the DP hypothesis: Phrases like “the toys,” “a red phone,” or “my dog” should be labelled as DPs (Determiner Phrases) because their heads are “the,” “a,” and “my,” which are called determiners in modern generative syntax.

This is fairly counterintuitive, to say the least. The intuitive hypothesis—the one that pretty much every linguist accepted until the 1980s—is that those phrases are NPs (Noun Phrases), but if we only accepted intuitive proposals, there’d be no science to speak of. Indeed, the all the good scientific theories start off counterintuitive and become intuitive only by force of argument. One of the joys of theory is experiencing that shift of mind-set—it can feel like magic when done right.

So it was quite unnerving when I started reading the actual arguments for the DP hypothesis, which I had, at one point, fully bought into, and and began to become less convinced by each one. It didn’t feel like magic, it felt like a con.

My source for this is a handbook chapter by Judy Bernstein that summarizes the basic argument for the DP Hypothesis—a twofold argument consisting of a Parallelism argument and purported direct evidence of the DP Hypothesis— as previously advanced sand developed by Szabolcsi, Abney, Longobardi, Kayne, Bernstein herself, and others.

The parallelism argument is based on another counterintuitive theory developed in in the mid-20th century which states that clauses, previously considered either headless or VPs, are actually headed by abstract (i.e., silent) words. That is, they are variously considered TPs (Tense Phrases), IP’s (Inflection Phrases), or CPs (Complementizer Phrases). The parallelism argument states that “if clauses are like that, then ‘noun phrases’ be like that too” and then finds data where “noun phrases” look like clauses in some way. This might seem reasonable on its face, but it’s a complete non sequitur. Maybe the structure of a “noun phrase” parallels that of a clause, but maybe it doesn’t. In fact, there’s probably good reason to think that the structure of “noun phrases” is the inverse of the structure of the clause—the clause “projects” from the verb, and verbs and nouns are complementary, so shouldn’t the noun have complementary properties to the verb?

Following through on parallelism, if extended VPs are actually CPs, then extended NPs are DPs. Once you have that hypothesis, you can start making “predictions” and checking if the data supports them. And of course there is data that becomes easy to explain once we have the DP Hypothesis. Again, this is good as far as it goes, but there’s a key word missing—”only.” We need data that only becomes easy to explain once we have the DP Hypothesis. And while I don’t have competing analyses for the data adduced for the DP Hypothesis at the ready—though Ben Bruening has one for at least one such phenomenon—I’m not really convinced that none exist.

And that’s the foundation of the DP Hypothesis, a weak argument resting on another weak argument. Yet, it’s a sticky one—I can count on one hand the contemporary generative syntacticians that have expressed skepticism about it. Why is it so sticky? My hypothesis is that it’s useful as a shibboleth and as a “project pump”.

Its usefulness as a shibboleth is fairly straightforward—there’s no quicker way to mark yourself as a generative syntactician than to put DPs in your tree diagrams. Even I find it jarring to see NPs in trees.

To see the utility of the DP Hypothesis as a “project pump”, one need only to look at the Cartography/Nanosyntax literature. Once you open up a space for invisible functional heads between N and D, you seem to find them everywhere. This, I think, is what Chomsky meant when he described the DP Hypothesis as “…very fruitful, leading to a lot of interesting
work” before saying “I’ve never really been convinced by it.” Who cares if it’s correct, it contains infinite dissertations!

Now maybe I’m being to hard on the DP and its fans. After all, as far as theoretical avenues go, the DP Hypothesis is something of a cul de sac, albeit a large one—the core theory doesn’t really care whether “the bee” is a DP or and NP, so what’s the harm? I could point out that by making such a feeble hypothesis our standard, we’ve opened ourselves to being dunked on my anti-generativists. Or I could bore you with such Romantic notions as “calling all things by their right names.” Instead, I’ll be practical and point out that, contrary to contemporary digital wisdom, the world is not infinite, and every bit of real estate given to the DP cul-de-sac in the form of journal articles, conference presentations, tenure-track hires, etc. is space that could be used otherwise. And, to torture the metaphor further, shouldn’t we try to use our real estate for work with a stronger foundation?

Canada’s double standard in Israel-Palestine

The Canadian government will “continue to follow the case very closely.” Those were the words of Canada’s Minister of Foreign Affairs Mélanie Joly in response to The ICJ’s preliminary findings in South Africa’s genocide case against Israel. She does not mention of the fact that court’s preliminary orders indicate that charges of genocide against Israel are not, as Liberal MP Anthony Housefather puts it, “baseless.” Nor does she indicate any move to withdraw Canada’s support of Israel, or even make it contingent on Israel even pretending to comply with the court’s order that it prevent acts of genocide, acts such as murdering three palestinians in Gaza less than a day after being ordered to prevent such acts.

Compare this to the decision to pause funding of UNRWA—the UN agency responsible for providing relief to Palestinian refugees—following allegations by the Israeli government that UNRWA employees participated in the events of October 7th. For it’s part, UNRWA immediately fired three staff members and initiated an investigation. But instead of offering platitudes about watching the process closely, Minister of International Development Ahmed Hussen, immediately paused funding for UNRWA.

So, in one case, we have a legitimate international court saying that, upon hearing arguments for and against, there is a prima facie plausible case against the State of Israel on the charge of genocide, and Canada adopts a wait-and-see approach, even as Israel appears to be ignoring the court. While in another case, we have mere allegations against employees of a UN agency, and Canada’s response is immediate action against the UN agency, even as the agency appears to be taking these allegations very seriously.

The double standard couldn’t be more plain.

Wrapping up 2023 with thanks, a pledge, and a humble request

As we approach the end of this year, I’ve had some time to reflect on my experience writing this blog, an experience that has been an overall positive. It’s allowed me to explore various ideas that would not have fit cleanly in any traditional academic linguistics forums—either because they are out of step with the mainstream, too nebulous, or either loosely or not-at-all related to linguistics. It’s opened a few doors for me that may not have been otherwise opened for me. And it’s given me an opportunity to interact with folks that I might not have otherwise. For this, I’m grateful and I want to extend a thank you to everyone who reads this blog and everyone who has reached out to me about its content, either in the comments or over email.

I’ve also decided that I need to write and publish more regularly, so starting in 2024, I plan to post a bit of writing at least once every two weeks.

Finally, I’ve realized how happy I am to have (relatively) complete control over my publishing platform especially as I see corporate-controlled platforms continually “pivot” to try to profit off of writers’ work. Having control over my platform, however, has costs—server costs, that is. I’d rather not run ads beside my work, and I’m not yet ready to run a Patreon (or equivalent), so in the mean time, I have a request for you. If you’ve enjoyed my writing thus far and have the means, please consider extending some financial support here: https://www.buymeacoffee.com/milway. Any little bit will be greatly appreciated.

Thank you for reading, and I’ll see you in 2024!

Piantadosi and MLMs again (I)

Last spring, Steven Piantadosi, professor of psychology and neuroscience, posted a paean to Modern Language Models (MLMs) entitled Modern language models refute Chomsky’s approach to language on LingBuzz. This triggered a wave of responses from linguists, including one from myself, pointing out the many ways that he was wrong. Recently, Prof. Piantadosi attached a postscript to his paper in which he responds to his critics. The responses are so shockingly bad, I felt I had to respond—at least to those that stem from my critiques—which I will do, spaced out across a few short posts.

In my critique, I brought up the problem of impossible languages, as did Moro et al. in their response. In addressing this critique, Prof. Piantadosi surprisingly begins with a brief diatribe against “poverty of the stimulus.” I say surprisingly, not because it’s surprising for an empiricist to mockingly invoke “poverty of stimulus” much in the same way as creationists mockingly ask why there are still apes if we evolved from them, but because poverty of stimulus is completely irrelevant to the problem of impossible languages and neither I nor Moro et al. even use the phrase “poverty of stimulus.”[1]For my part, I didn’t mention it because empiricists are generally quite assiduous in their refusal to understand poverty of stimulus arguments.

This irrelevancy expressed, Prof. Piantadosi moves on to a more on-point discussion. He argues that it would be wrong-headed for the constraints that would make some languages impossible to be encoded in our model from the start. Rather, if we start with an unconstrained model, we can discover the constraints naturally:

If you try to take constraints into account too early, you might have a harder time discovering the key pieces and dynamics, and could create a worse overall solution. For language specifically, what needs to be built in innately to explain the typology will interact in rich and complex ways with what can be learned, and what other pressures (e.g. communicative, social) shape the form of language. If we see a pattern and assume it is innate from the start, we may never discover these other forces because we will, mistakenly, think innateness explained everything

p36 (v6)

This makes a certain intuitive sense. The problem is that it’s refuted both by the history of generative syntax and the history of science more broadly.

In early theories, a constraint like “No mirroring transformations!” would have to be stated explicitly. Current theories, though, are much simpler with most constraints being derivable from the theory rather than tacked onto the theory.

A digression on scholarly responsibility: Your average engineer working on MLMs could be forgiven for not being up on the latest theories in generative syntax, but Piantadosi is an Associate Professor who has chosen to write a critique of generative syntax, so he really ought to know these things. In fact, he would only not know these thing by a conscious choice not to know or laziness.

Furthermore, the natural sciences have progressed thus far in precisely the opposite direction as what Piantadosi prescribes—they have started with highly constrained theories and progress has generally occurred when some constraint is questioned. Copernicus questioned the constraint that Earth stood still, Newton questioned the constraint that all action was local, Friedrich Wöhler questioned the constraint that organic and inorganic substances were inherently distinct.

None of this, of course, means that we couldn’t do science in the way that Piantadosi suggests—I think Feyerabend was correct that there is no singular Scientific Method—but the proof of the pudding is in the eating. Piantadosi is effectively making a promise that if we let MLM research run its course we will find new insights[2]He seems to contradict himself later on when he asserts that the “science” of MLMs may never be intelligible to humans. More on this in a later post. that we could not find had we stuck with the old direction of scientific progress, and he may be right—just as AGI may actually be 5 years away this time—but I’ll believe it when I see it.


After expressing his methodological objections to considering impossible languages, Piantdosi expresses skepticism as to the existence of impossible languages, stating ” More troubling, the idea of “impossible languages” has never actually been empirically justified.” (p37, v6) This is a truly astounding assertion on his part considering both Moro et al. and I explicitly cite experimental studies that arguable provide exactly the empirical justification that Piantadosi claims does not exist. Both studies cited present participants with two types of made-up languages—one which follows and one which violates the rules of language as theorized by generative syntax—and observes their responses as they try to learn the rules of the particular languages. The study I cite (Smith and Tsimpli 1995) compares the behavioural responses of a linguistic savant to those of neurotypical participants, while the studies cited by Moro et al. (Tettamanti et al., 2002; Musso et al., 2003) uses neuro-imaging techniques. Instead Prof. Piantadosi refers to every empiricists favourite straw-man argument—the alleged lack of embedding structures in Pirahã.

This bears repeating. Both Moro et al. and I expressly point to experimental evidence of impossible languages, and Piantadosi’s response is that no one has ever provided evidence of impossible languages.

So, either Prof. Piantadosi commented on mine and Moro et al‘s critiques without reading them, or he read them and deliberately misrepresented them. It is difficult to see how this could be the result of laziness or even willful ignorance rather than dishonesty.

I’ll leave off here, and return to some of Prof. Piantadosi’s responses to my critiques at a later time.

Notes

Notes
↑1 For my part, I didn’t mention it because empiricists are generally quite assiduous in their refusal to understand poverty of stimulus arguments.
↑2 He seems to contradict himself later on when he asserts that the “science” of MLMs may never be intelligible to humans. More on this in a later post.

A response to Piantadosi (2023)

(Cross-posted on LingBuzz.)

It is perhaps an axiom of criticism that one should treat the object of criticism on its own terms. Thus, for instance, a photograph should not be criticized for its lack of melody. This axiom makes it difficult to critique a recent paper by Steven Piantadosi—hereafter SP—as it is difficult to determine what its terms are. It is ostensibly the latest installment of the seeming perennial class of papers that argue on the basis of either a new purported breakthrough in so-called AI or an exotic natural language dataset that rationalist theories of grammar are dead wrong, but it actually is a curious mix of criticism of Generative Grammar, promissory notes, and promotion for OpenAI’s proprietary ChatGPT chatbot.

The confusion begins with the title of the paper in (1) which doubles as its thesis statement and contains a category error.

(1) Modern language models refute Chomsky’s approach to language.

To refute something is show that it is false, but approaches do not have truth values. One can refute a claim, a theory, or a hypothesis, and one can show an approach to be ineffective, inefficient, or counterproductive, but one cannot refute an approach. The thesis of the paper under discussion, then, is neither true nor false, and we could be excused for ignoring the paper altogether.

Another axiom of criticism, though, is the principle of charity, which dictates that we present the best possible version of the object of our criticism. To that end we can split up (1) into two theses (2) and (3).

(2) Modern language models refute Chomsky’s theories language.
(3) Modern language models show Chomsky’s approach to language to be obsolete.

It is these theses that I address below.

The general shape of SP’s argument is as follows: (A) Chomsky claims that adult linguistic competence cannot be attained or simulated on the basis of data and statistical analysis alone. (B) The model powering ChatGPT simulates adult linguistic competence on the basis of data and statistical analysis alone. Therefore, (C) The model powering ChatGPT shows Chomsky’s claims to be false. To support his argument, SP presents queries and outputs from ChatGPT and argues that each refutes or approaches a refutation of a specific claim of Chomsky’s—each argument is of the form “Chomsky claims a purely statistical model could never do X, but ChatGPT can do (or can nearly do) X.”

As the hedging in this summary indicates, SP admits there are some phenomena for which ChatGPT does not exhibit human-like behaviour. For instance, when SP prompts the chatbot to generate ten sentences like (4), the program returns ten sentences all of which share the syntactic structure of (4), none of which are wholly meaningless like (4).

(4) Colorless green ideas sleep furiously.

SP explains this as away, writing “[w]e can note a weakness in that it does not as readily generate wholly meaningless sentences …, likely because meaningless language is rare in the training data.” Humans can generate meaningless language, despite the fact that is “rare in the
training data” for us too. The autonomy of syntax, then, is an instance where OpenAI’s language model does not exhibit human-like behaviour. Furthermore, SP notes that current models require massive amounts of data to achieve their results—amounts far outstripping the amount of data available to a child. He also notes that the data is qualitatively different from that available to a child.[1]SP also wrongly implies that the data that informs actual language acquisition consists of child-directed speech. In doing so, he admits that modern language models (MLMs) are not good models of the human language faculty, contradicting one of the premises of his argument.

Though these empirical shortcomings of models like the one powering ChatGPT quite plainly refute (2), we do not even need such evidence to do so, as (2) is self-refuting. It is self-refuting because it does not address theoretical claims that Chomsky or, to my knowledge, any
Generative theoretician has made. Far from claiming that MLMs could never do the things that ChatGPT can do, Chomsky has repeatedly claimed the opposite—that with enough data and computing power, a statistical model would almost certainly outperform any scientific theory in terms of empirical predictions. Indeed, this is the point of one the quotes that SP includes:

You can’t go to a physics conference and say: I’ve got a great theory. It accounts for everything and is so simple it can be captured in two words: “Anything goes.”

All known and unknown laws of nature are accommodated, no failures. Of
course, everything impossible is accommodated also.

Furthermore, Generative theories are about a component of human cognition[2]This is the crux of the I-/E-language distinction that Chomsky often discusses., and nowhere does SP claim that “modern language models” are good models of human cognition. Indeed, this is an extension of the above discussion of the data requirements of MLMs, and logically amounts to a claim that the supposed empirical successes of MLMs are illusory
without biological realism.

So, SP does not show that MLMs refute Chomsky’s theory, but what of his approach to language? Here we can look at the purported successes of MLMs. For instance, SP presents ChatGPT data showing grammatical aux-inversion in English, but provides no explanation as to how it achieves this. Such an explanation though, is at the core of Chomsky’s approach to language. If MLMs do not provide an explanation, then how can they supplant Chomsky’s approach?

The failure of MLMs to supplant Chomsky’s approach can be demonstrating by extending one of SP’s metaphors. According to SP, the approach to science used by MLMs is the same that is used to model and predict hurricanes and pandemics. Let’s assume this is true, it is also true
that meteorological and epidemiological models have at their cores, equations arrived at by theoretical/explanatory work done by physicists and biologists respectively. If MLMs supplant theoretical/explanatory linguistics, then hurricane and pandemic models should supplant physics and biology. No serious person would make this argument about physics or
biology, yet it is fairly standard in linguistics.

Thus far we have been taking SP’s data at face-value, and while there is absolutely no reason to believe that SP has falsified it in any way, there is still a serious problem with it—it is, practically speaking, unreplicable, since we have no access to the model that generated it.
The data in the paper was generated by ChatGPT in early 2023. When it was initially released, ChatGPT worked with the GPT 3.5 model, and has since been migrated to GPT 4—both of which are closed-source. So, while SP adduces ChatGPT data as evidence in favour of the sort of
models that he has developed as his research program, there is no way to know whether ChatGPT uses the same sort of model. Indeed, ChatGPT could be built atop a model based on Generative theories of language for all we know.

Returning to the axiom I started with—that one should criticize something on its own terms—The ultimate weakness of SPs paper, is its failure to follow it. Chomsky’s main critique of MLMs—alluded to in the quote above—is not that they are unable to produce grammatical expressions. It’s that if they were to be trained on data from an impossible language—a language that no human could acquire—they would “learn” that language just as easily as, say, English. One does
not need to look very far to find Chomsky saying exactly this. Take, for instance, the following quote in which Chomsky responds to a request for his critique of current so-called AI systems.[3]Taken from extemporaneous speech. Edited to remove false starts and other disfluencies. Source: https://www.youtube.com/watch?v=PBdZi_JtV4c

There’s two ways in which a system can be deficient. One way is it’s not strong enough—[it] fails to do certain things. The other way is it’s too strong—it does what it shouldn’t do. Well, my own
interests happen to be language and cognition—language specifically. So take GPT. Gary Marcus others have found lots of ways in which the system’s deficient—this system and others—[it] doesn’t do certain things. That can in principle at least be fixed—you add another trillion parameters double the number of terabytes and maybe do better. When a system is too strong it’s unfixable typically and that’s the problem with GPT and the other systems.

So if you give a database to the GPT system which happens to be from an impossible language—one that violates the rules of language—they’ll do just as well—often better because the rules can be simpler. For example one of the fundamental properties of the way language works—there’s good reasons for it—is that the rules the core rules ignore linear order of words—they ignore everything that you hear. They attend only to abstract structures that the mind creates So it’s very easy to construct impossible languages which use very simple procedures involving linear order of words [The] trouble is that’s not language but GPT will do just fine with them. so it’s kind of as if somebody were to propose uh say a revised version of the of the periodic table which included all the elements all the possible elements and all the impossible elements and didn’t make any distinction between them that wouldn’t tell us anything about elements. And if a system works just as well for impossible languages as for possible ones by definition not telling us anything about language. And that’s the way these systems—work it generalizes the other systems too. So the deep problem that concerns me is too much strength. I don’t see any conceivable way to remedy that.

The key notion here is that of an “impossible language” which, though it seems to have an a priori flavour to it, is actually an empirical notion. Generative theory, like every scientific theory, predicts not only what is possible, but what is impossible? For instance, generative theory predicts that linear order is not available to syntax, and therefore no language has grammatical rules based on linear order. SP indirectly addresses this concern:

It’s worth thinking about the standard lines of questioning generative syntax has pursued—things like, why don’t kids ever say “The dog is believed’s owners to be hungry” or “The dog is believed is hungry” […]. The answer provided by large language models is that these are not permitted under the best theory the model finds to explain what it does see. Innate constraints are not needed.

Following this standard empiricist reasoning, there are no impossible languages, only languages which have yet to be seen.[4]Setting aside languages which are logical impossibilities, like a
language which has and lacks determiners.
If all we had to go on was description of actually existing languages, then the empiricist and rationalist accounts would be equally plausible. Luckily for us, we are not limited in this way, we have experimental results that directly support the rationalist accounts—Smith and Tsimpli (1995), for instance, provides evidence that, while we can learn “impossible languages”, we do so in a fundamentally different way than we learn possible languages, with the former treated like puzzles rather than languages.

To summarize, SP purports to show that MLMs refute Chomsky’s approach to language—a logical impossibility. What he does show is that there are multiple aspects adult English competence that ChatGPT is unable to simulate, and the in the cases where ChatGPT was able to mimic an adult English speaker, there is no explanation as to how. Neither of these results are germane to either Chomsky’s approach to language or his theories of language, as Chomsky studies the human capacity for language, which MLMs tell us nothing about. More importantly, SP does not even address Chomsky’s actual critique of MLM qua models of
language competence.
Notes

Notes
↑1 SP also wrongly implies that the data that informs actual language acquisition consists of child-directed speech.
↑2 This is the crux of the I-/E-language distinction that Chomsky often discusses.
↑3 Taken from extemporaneous speech. Edited to remove false starts and other disfluencies. Source: https://www.youtube.com/watch?v=PBdZi_JtV4c
↑4 Setting aside languages which are logical impossibilities, like a
language which has and lacks determiners.

On pop-culture and our appetite for complexity

(A slightly edited version of a series of posts on Twitter)

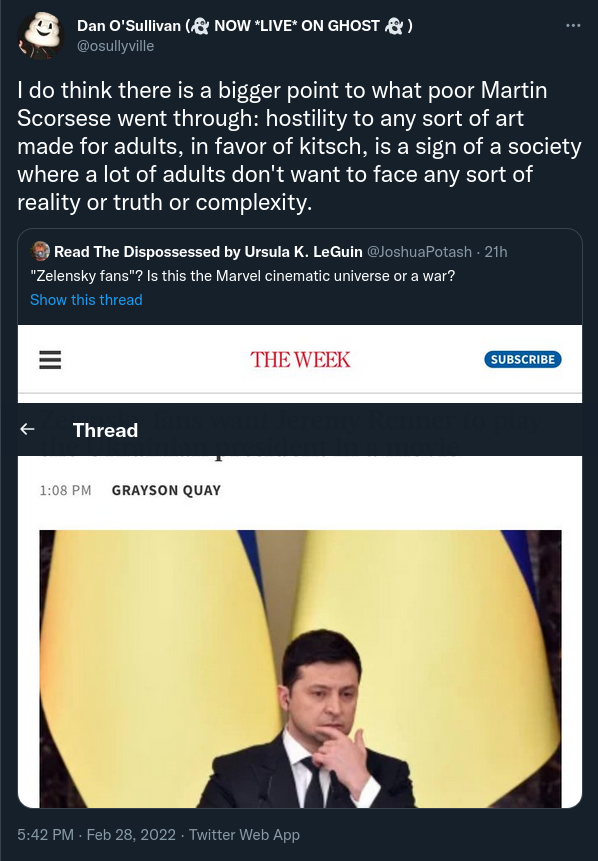
There’s something to this take by Dan O’Sullivan, but I actually think part of the appeal of Marvel movies etc. is that they’re complex. In fact, I think one of the defining characteristics of popular 21st century film/TV is complexity.

A tweet from Dan O’Sullivan (@osullyville)

Lost, Game of Thrones, the MCU, Star Wars, they’re all complicated world-building exercises, and that’s what people love about them. They revel in the web of plot and characters.

It reminds me of an observation that Chomsky made once about sports talk radio:

When I’m driving, I sometimes turn on the radio and I find very often that what I’m listening to is a discussion of sports. These are telephone conversations. People call in and have long and intricate discussions, and it’s plain that quite a high degree of thought and analysis is going into that. People know a tremendous amount. They know all sorts of complicated details and enter into far-reaching discussion about whether the coach made the right decision yesterday and so on. These are ordinary people, not professionals, who are applying their intelligence and analytic skills in these areas and accumulating quite a lot of knowledge and, for all I know, understanding. On the other hand, when I hear people talk about, say, international affairs or domestic problems, it’s at a level of superficiality that’s beyond belief.

Noam Chomsky: Why Americans Know So Much About Sports But So Little About World Affairs

The people who call in to these shows are not necessarily highly educated, but they’re able to give very sophisticated and well-thought-out analysis of baseball or hockey, or whatever, but ask the average person, even a well-educated person about world affairs, and you’ll get some very shallow platitudes. People are smart. They like understanding complex things. And, more importantly, they like debating and engaging with complexity.

The governing principle of most “democracies,” though is that the political and business bosses do the thinking, and the rest of us should butt out.

Any attempt on our part to engage with, debate, or affect anything that matters is met with ridicule at best and tear-gas, truncheons, or bullets at worst.

So, the MCU didn’t make us dumb. It merely absorbed our natural impulse to engage with complexity, and, in doing so, distracted us from the complexity that really matters.

Coming back to O’Sullivan’s point: With complex works of fiction created by massive corporations, the choice of which aspects are simple and which are complex is up to their creators. So naturally, they’ll make those choices according to their own interests.

Conflict is between individual heroes and villains, and we can identify with or revile them, but certainly not the mass of people threatened by the villains or defended by the heroes.

Video essayist Evan Puschak, AKA The Nerdwriter, gives a similar analysis:

Of course, there’s another question lurking: Don’t the more artsy films serve the same function? Doesn’t SILENCE or THE LIGHTHOUSE just distract us from the real problems too? Maybe, but, if it’s done well, I think not.

I think the key ingredient of fiction that subverts that function is ambiguity. World-building fiction presents a complete closed system. nothing in or out. Ambiguity forces us to actively interpret, and to do so under uncertainty.

To resolve such ambiguity, we have to bring our experience (of the real world) into the fiction, and that necessarily means examining our own experience, to some extent.

It doesn’t give us the tools to understand geopolitics, it gives us the tools to be okay with the ambiguity.

Originally tweeted by Dan Milway (@thrilway) on March 1, 2022.

Some idle thoughts on the arguments for semantic externalism/internalism

This semester I’m teaching an intro semantics course for the first time and I decided to use Saeed’s Semantics as a textbook. Its seems like a good textbook; it gives a good survey of all the modern approaches to semantics—internalist, externalist, even so-called cognitive semantics—though the externalist bias is clear if you know what to look for. For instance, the text is quick to bring up the famous externalist thought experiments—Putnam’s robotic cats, Quine’s gavagai, etc—to undercut the internalist approaches, but doesn’t really seem to present the internalist critiques and counterarguments. So, I’ve been striving to correct that in my lectures.

While I was preparing my most recent lecture, something struck me. More precisely, I was suddenly able to put words to something that’s bothered me for a while about the whole debate: The externalist case is strongest for natural kinds, but the internalist case is strongest for human concepts. Putnam talks about cats and water, Kripke talks about tigers and gold, while Katz talks about bachelors and sometimes artifacts. This is not to say that the arguments on either side are unanswerable—Chomsky, I think has provided pretty good arguments that even, for natural kinds, our internal concepts are quite complicated, and there are many thorny issues for internalist approaches too—but they do have slightly different empirical bases, which no doubt inform their approach—if your theory can handle artifact concepts really well, you might be tempted to treat everything that way.

I don’t quite know what to make of this observation yet, but I wanted to write it down before I forgot about it.


There’s also a potential, but maybe half-baked, political implication to this observation. Natural kinds, are more or less constant in that, while they can be tamed and used by humans, we can’t really change them that much, and thinking that you can, say, turn lead into gold would mark you as a bit of a crackpot. Artifacts and social relations, on the other hand, are literally created by free human action. If you view the world with natural kinds at the center, you may be led to the view that the world has its own immutable laws that we can maybe harness, maybe adapt to, but never change.

If, on the other hand, your theory centers artifacts and social relations, then you might be led to the conclusion, as expressed by the late David Graeber, that “the ultimate hidden truth of the world is that it is something we make and could just as easily make differently.”

But, of course, I’m just speculating here.

But it’s obvious, isn’t it?

As a linguist or, more specifically, as a theoretical syntactician, I hold and often express some minority opinions.[1]Outside of syntactic theory too Often these opinions are met with bafflement and an assertion like “We’ve known for years that that’s not the case” because of this phenomenon, or that piece of data—“Control is derived by movement? But what about de se interpretation??” “Merge is free? But what about c-selection??” “Long-distance Agree isn’t real? But what about English existential clauses??”[2]I have a hypothesis that the vehemence with which someone will defend a theory or analysis is correlated with how much they struggled to understand it in school. Basically, we’re more likely to … Continue reading These sorts of objections are often tossed out as if the data speaks for itself when really, the thing that makes scientific inquiry so tough is that the data rarely speaks for itself, and when it does, it doesn’t do so clearly.

Take, for instance, the case of English existential clauses like (1) and (2) and how they are used as absolute proof of the existence of Long-Distance Agree.

(1) There ?seems/seem to be several fish in the tank.
(2) There seems/*seem to be a fish in the tank.

In both sentences, the grammatical subject is the expletive there, but the verb agrees with a DP[3]I still think I buy the DP hypothesis, but I’m also intrigued by Chomsky’s recent rejection of it and amused by the reaction to this rejection. that appears to be structurally “lower” in the clause. Therefore, there must be some non-movement way of getting features from a lower object onto a higher object—Long-Distance Agree. This is often presented as the obvious conclusion, the only conclusion, or the simplest conclusion. “Obvious” is in the eye of the beholder and doesn’t usually mean “correct”; Norbert Hornstein, in his A Theory of Syntax proposes three alternative analyses to Long-Distance Agree; only “simplest” has legs, although that’s debatable.

Occam’s razor says “entities should not be multiplied without necessity,” and any analysis of (1) and (2) without Long-Distance Agree will have to say that in both cases, the agreeing DP is covertly in subject position. These covert subjects are argued to constitute an unnecessary multiplication of entities, but one could just as easily argue that Long-Distance Agree is an unnecessary entity. What’s more, covert movement and silent elements both have independent arguments in their favour.

Of course, the covert subject analysis of (1) and (2) is not without its flaws. Chief among them, in my opinion, is that it would seem to wrongly predict that (1) and (2) mean the same thing as (3) and (4), respectively.

(3) Three fish seem to be in the tank.
(4) A fish seems to be in the tank.

These sentences differ from (1) and (2) in that they—(3) and (4)—presuppose the existence of three fish or a single fish, while (1) and (2) merely assert it. This contrast is clearest in (5)-(8) which are examples that Chomsky has been using for several decades.

(5) There’s a fly in my soup.
(6) There’s a flaw in my argument.
(7) A fly is in my soup.
(8) *?A flaw is in my argument.

Likewise, Long-Distance Agree has its own problems, some of which I discuss in my latest paper. Indeed, it is vanishingly rare in any field of inquiry—or life itself—to find an unproblematic solution to a problem.

My goal here isn’t to argue that Long-Distance Agree is wrong,[4]Though, I do think it is. but to point out that it’s not a foregone conclusion. In fact, I think that if we listed the hypotheses/theories/notions that most syntacticians took to be (nearly) unquestionable and honestly assessed the arguments in their favours, I doubt that many would turn out to be as robust as they seem. This doesn’t mean that we need to reject every idea that less than 100% solid, just that we should hold on to them a little more loosely. As a rule, we should all carry with us the idea that we could very well be wrong about almost everything. The world’s more interesting that way.

Notes

Notes
↑1 Outside of syntactic theory too
↑2 I have a hypothesis that the vehemence with which someone will defend a theory or analysis is correlated with how much they struggled to understand it in school. Basically, we’re more likely to die on a hill if we had to fight to summit that hill. This has some interesting implications that I might get into in a later post.
↑3 I still think I buy the DP hypothesis, but I’m also intrigued by Chomsky’s recent rejection of it and amused by the reaction to this rejection.
↑4 Though, I do think it is.

New LingBuzz Paper

(or “How I’ve been spending my unemployment*”)

Yesterday I finished and posted a paper to LingBuzz. It’s titled “Agree as derivational operation: Its definition and discontents” and its abstract is given below. If it sounds interesting, have a look and let me know what you think.

Using the framework laid out by Collins and Stabler (2016), I formalize Agree as a syntactic operation. I begin by constructing a formal definition a version of long-distance Agree in which a higher object values a feature on a lower object, and modify that definition to reflect various several versions of Agree that have been proposed in the “minimalist” literature. I then discuss the theoretical implications of these formal definitions, arguing that Agree (i) muddies our understanding of the evolution of language, (ii) requires a new conception of the lexicon, (iii) objectively and significantly increases the complexity of syntactic derivations, and (iv) unjustifiably violates NTC in all its non-vacuous forms. I conclude that Agree, as it is commonly understood, should not be considered a narrowly syntactic operation.

*Thanks to the Canada Recovery Benefit, I was able to feed myself and make rent while I wrote this.